<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://stephen.genoprime.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://stephen.genoprime.com/" rel="alternate" type="text/html" /><updated>2026-10-12T14:31:35+00:00</updated><id>https://stephen.genoprime.com/feed.xml</id><title type="html">stephen mallette</title><subtitle>stephen mallette - building graph technology</subtitle><entry><title type="html">Remembering Why in Apache TinkerPop</title><link href="https://stephen.genoprime.com/snippet/2026/10/12/snippet-28.html" rel="alternate" type="text/html" title="Remembering Why in Apache TinkerPop" /><published>2026-10-12T00:00:00+00:00</published><updated>2026-10-12T00:00:00+00:00</updated><id>https://stephen.genoprime.com/snippet/2026/10/12/snippet-28</id><content type="html" xml:base="https://stephen.genoprime.com/snippet/2026/10/12/snippet-28.html"><![CDATA[<p>Anyone who has developed software for any extended period of time knows the experience of looking at a piece of code at some point in the future and wondering why it is the way it is. The commit tells you what changed. The JIRA issue, if there is one, tells you what someone set out to do. A well disciplined project will likely have some good inline and structured code comments that provide some clues as to what the thinking was at the time. What almost never survives is the reasoning in between, like the approach that was tried first and abandoned, the option that looked obvious but had a hidden cost, or the trade-off that was accepted knowingly. Without that, a future maintainer either re-litigates a settled question or, worse, “fixes” something that was deliberate.</p>

<p>Working with agents makes this problem both worse and more solvable. Worse, because a great deal of design reasoning now happens in conversation with an agent, and that conversation disappears when the session ends. More solvable, because the agent is right there when the decision is made and can write it down at the moment it happens. In <a href="https://tinkerpop.apache.org/">Apache TinkerPop</a>, we’ve been using <a href="https://github.com/gastownhall/beads">Beads</a> to do exactly that.</p>

<h2 id="from-idea-to-practice">From idea to practice</h2>

<p>Back in April, in <a href="/snippet/2026/04/27/snippet-24.html">Long-term agentic memory in Apache TinkerPop using Beads</a>, I argued that the reasoning behind agent-driven work is an artifact in its own right, and that Beads, which I’d first come across while experimenting with <a href="/snippet/2026/04/03/snippet-23.html">Gastown</a>, could grow from a dependency aware agent issue tracker into a <strong>long-term memory</strong> by connecting decisions to the work they shaped. At the time, that was more of an idea than a practice. The example I used was a bead full of open questions about multi-label vertices, and the best I could say was that the path from those questions to their answers would be found in future connected beads, whenever they were made.</p>

<p>In the months since, I’ve worked out what those connected beads should actually look like and when an agent should write them. This post describes where TinkerPop and Beads landed.</p>

<p>Official project contributors have a straightforward means for setup, using <code class="language-plaintext highlighter-rouge">bin/agent-setup.sh --contributor</code> to wire up the workflow to their agent. The repository’s <code class="language-plaintext highlighter-rouge">AGENTS.md</code> tells any agent that, if the <code class="language-plaintext highlighter-rouge">bd</code> command is installed, it should run <code class="language-plaintext highlighter-rouge">bd prime</code> at the start of a session. That emits <a href="https://github.com/apache/tinkerpop/blob/master/.beads/PRIME.md"><code class="language-plaintext highlighter-rouge">.beads/PRIME.md</code></a>, which is the canonical description of how TinkerPop uses Beads.</p>

<p>A key guiding instruction in <code class="language-plaintext highlighter-rouge">PRIME.md</code> summarizes the logic that drives the agent:</p>

<blockquote>
  <p>Treat every bead as something a contributor will read in three years.</p>
</blockquote>

<h2 id="the-structure">The structure</h2>

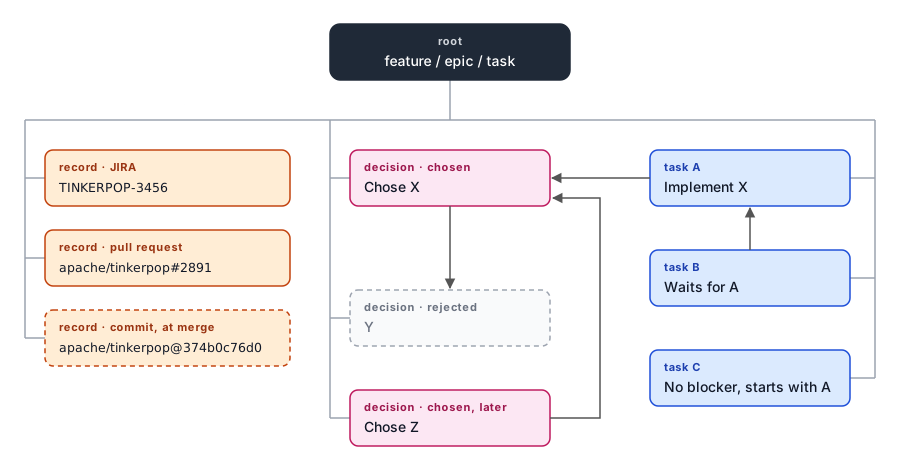
<p>Every piece of work hangs off a <strong>root bead</strong>, which is usually a feature, epic or task. Beneath it sit three kinds of children:</p>

<p><img src="/assets/images/beads-structure.svg" alt="The structure of a TinkerPop bead subtree" /></p>

<p><strong>Records</strong> hold the external artifacts, such as the JIRA issue, the pull request, a dev list thread, a proposal and, once the work lands, the commits it merged as.</p>

<p><strong>Tasks</strong> are the work itself, and an agent plans them natively as beads in a graph rather than just Markdown text. As a graph, edges create workflows that allow tasks to run in parallel, block on given dependencies, wait for human interaction or simply follow a chain of work. This is typically how Beads is used.</p>

<p><strong>Decisions</strong> tend to come in pairs and represent the choices made while developing the work itself. A decision’s reasoning is never edited in place. If the thinking changes, a new decision is created with a <code class="language-plaintext highlighter-rouge">supersedes</code> edge to the old one, so the record shows not only where the design ended up but how it got there.</p>

<h2 id="capturing-the-road-not-taken">Capturing the road not taken</h2>

<p>A decision bead records a choice and its reasoning. TinkerPop’s approach goes a step further in that that every chosen decision is typically paired with a <strong>rejected</strong> sibling, connected by a <code class="language-plaintext highlighter-rouge">related</code> edge. The chosen decision says why it won and what it rules out. The rejected one says what the alternative concretely was, why it lost and what settled it.</p>

<p>Knowing when to write one is the tricky part, so <code class="language-plaintext highlighter-rouge">PRIME.md</code> doesn’t leave it to judgment. It names five observable events that signal a decision has happened:</p>

<ol>
  <li>The operator redirects the agent, as in “no, do X instead” or “we tried that.”</li>
  <li>What was built diverged from the JIRA, the proposal or the dev list thread.</li>
  <li>An approach was tried and abandoned.</li>
  <li>The agent presented options.</li>
  <li>A discovery contradicted an assumption.</li>
</ol>

<p>If something was considered and not chosen, it gets a decision and a rejected sibling. If something is just true, like a measurement or a constraint, it goes in a comment on the root instead. The rejected thing doesn’t have to be a grand design either. Declining to implement a certain body of tests or opting to write documentation of greater scope than the work initially intended are both relevant sorts of rejections.</p>

<p>There are a couple of rules around this that I’ve found make a real difference in the quality of what gets recorded. The first is that a rejected alternative’s reason must be a mechanism rather than a judgment. A mechanism is like the cause and effect that made the option fail. It is stated in terms of the code or the situation rather than an opinion about it. A reason such as “Too slow” is a judgment and it helps a future reader little in the future. On the other hand, “Every lookup has to scan the whole log, so reads get slower as the graph grows” is a mechanism. The first leaves nothing to check, while the second names a specific condition. If someone later adds an index that removes the scan, they can see right away that the old objection no longer applies.</p>

<p>The second rule is that if the agent can’t say why I rejected something, it has to ask before writing the bead. An incorrectly inferred reason looks exactly like a factual one three years later. Asking while the conversation is still live is the only way to get it right.</p>

<h2 id="what-it-looks-like-in-practice">What it looks like in practice</h2>

<p>The work on TinkerGraph’s new durable storage, in <a href="https://github.com/apache/tinkerpop/pull/3639">#3639</a>, produced 52 beads, 33 of which were decisions and 17 of those rejected alternatives. A simple example of rejected alternative came up while planning a leaner on-disk format. The agent recommended bumping the storage format version, so that a store written in the older format would present an error rather than misread. I overrode it, and the rejected bead records why. Nothing had been released yet, so there was no existing store to protect, and the machinery for two formats to coexist would have been unnecessary work. The bead ends by noting that the question should be reconsidered once the format ships, since the version byte is still there to bump when it matters.</p>

<p>That one bead does a few things at once. It captures me redirecting the agent, which is the strongest signal that a decision happened. Its reason is a mechanism, since “nothing is released” is a fact anyone can check. In addition, it names a condition that will actually arrive. The first time someone changes the format after 4.0.0 ships, the bead tells them the version bump was deliberately deferred and not simply forgotten.</p>

<p>A smaller example concerned a configuration key. The storage directory was originally configured with <code class="language-plaintext highlighter-rouge">gremlin.tinkergraph.graphLocation</code>, inherited from 3.x, and the decision to rename it to <code class="language-plaintext highlighter-rouge">gremlin.tinkergraph.storage.directory</code> was paired with a rejected sibling for keeping the old name. The rejected bead explains that the continuity would have been nominal rather than behavioral. In 3.x the key named a file that drove automatic loading and saving, which 4.x removed, so keeping the familiar name would have preserved recognition while the behavior it named was gone. Should someone in the future wonder what happened to <code class="language-plaintext highlighter-rouge">gremlin.tinkergraph.graphLocation</code>, they will get a full accounting of the situation without having to comb through commits trying to piece the story together.</p>

<h2 id="memory-for-people-and-for-agents">Memory for people and for agents</h2>

<p>Every long-lived project has its lore. It is the knowledge of why things are the way they are, like the approach that was tried years ago and abandoned, or the odd-looking compromise that keeps something else from breaking. Lore rarely makes it into documentation. It lives in the heads of the people who were there, and the only way to get at it is to ask them, assuming they are still around and still remember. TinkerPop has been going for over fifteen years, and over that time contributors have come and gone, each taking a bit of that lore with them.</p>

<p>What Beads gives TinkerPop is a way to write that lore down at the moment it is created, while the reasoning is still fresh, and attach it to the work it shaped. Why something was done, and why the alternatives weren’t, no longer depends on someone remembering it.</p>

<p>This knowledge serves two audiences. A contributor revisiting a design can read the decisions and the paths not taken and understand the shape of the code without having been in the room. An agent working on that code later can do the same, which is arguably even more important, since an agent has no memory of past sessions at all unless something like this gives it one. In a sense, every contributor, human or agent, now has someone to ask who was there.</p>]]></content><author><name></name></author><category term="snippet" /><summary type="html"><![CDATA[How Apache TinkerPop uses Beads to record its design decisions, and the alternatives it rejected, as lasting project memory.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://stephen.genoprime.com/assets/images/gremlin-gastown-beads.png" /><media:content medium="image" url="https://stephen.genoprime.com/assets/images/gremlin-gastown-beads.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Micro Pull Requests, and Who Reads Documentation Now</title><link href="https://stephen.genoprime.com/snippet/2026/08/05/snippet-27.html" rel="alternate" type="text/html" title="Micro Pull Requests, and Who Reads Documentation Now" /><published>2026-08-05T00:00:00+00:00</published><updated>2026-08-05T00:00:00+00:00</updated><id>https://stephen.genoprime.com/snippet/2026/08/05/snippet-27</id><content type="html" xml:base="https://stephen.genoprime.com/snippet/2026/08/05/snippet-27.html"><![CDATA[<p>An interesting, and mostly unplanned, side-effect of the ongoing advancement of my personal agent orchestration system is that it has organized itself to produce high quality pull requests for <a href="https://tinkerpop.apache.org/">Apache TinkerPop’s</a> documentation. What I’ve found fascinating about these pull requests is that they are the polar opposite to the massive thousand line diff types agents can so easily produce for us and that we struggle to review and integrate into production. In contrast, these pull requests are small, usually affecting one file, and create a diff of 10 lines or less, making them astoundingly easy to review and merge quickly. I’ve found them to be of high value despite their size. I accidentally referred to them in a discussion with colleagues as <strong>Micro Pull Requests (MPR)</strong>, as way to make their tiny stature stand out in a time where the idea of greater review burdens from agent generated content creates collective groaning sounds from the engineers who need to examine them. There is much discussion about the amazing, large bodies of code being produced by agents and how to handle that, but I think there is room to think about the MPR a bit as we continue to figure out how we can use agents to accelerate and expand our work.</p>

<p>What makes this worth writing about is not only the shape of the contributions, but where they come from. The same shift that put agents to work repairing documentation also put them to work reading it, and that second role is quietly changing what documentation is for and how much it costs us when it is wrong.</p>

<h2 id="the-agent-system-behind-the-pull-requests">The agent system behind the pull requests</h2>

<p>In a prior blog post titled <a href="/snippet/2026/06/01/snippet-25.html">Graphs, Agents, and the Characters Between</a>, I described the importance of metaphor to help ground human connection to complex systems. One of the metaphors that I detailed was the one I use for operating my personal multi-agent orchestration system, a home grown tool that features characters like Monkeys for workers, a Toucan to help manage infrastructure and a Hammock from which I direct the work of this rain forest-inspired veil for an agent interface. Since the time of that writing, I’ve expanded the jungle considerably with a swimming pool area as an alternative place monkeys work, which correlates to a scalable, emphemeral remote agent instance set and a “human” administrative assistant, naming herself Miss Pemberton, who serves as the long-term memory for the jungle mapping to an <a href="https://www.ironclaw.com/">IronClaw</a> instance, handling reporting, automation and other tasks I want to offload.</p>

<p>It’s worth clarifying that while Pemberton (she told me it was acceptable to drop the formality of “Miss” if I preferred) has a broad view of what’s happening across the system, she also serves as the memory of the jungle. Her role is both coordination and recall. She observes the activity of monkeys, tracks the changes applied by Toucan, and retains context across builds, tickets, and schedules so that nothing is lost to time. Where she becomes particularly useful is in how she translates that accumulated awareness into action.</p>

<h2 id="how-the-documentation-testing-works">How the documentation testing works</h2>

<p>One of the more effective responsibilities I’ve given her is ownership of an ongoing documentation testing effort against TinkerPop.</p>

<p>As Documentation Testing Manager, Pemberton identifies candidate sections of documentation and constructs test plans that frame a concrete goal based solely on what is written in the section. Because she maintains memory of what has already been tested, she avoids redundant effort and builds a growing ledger of coverage and findings over time. These plans are handed off to worker agents, monkeys operating in the pool, where isolation is cheap and parallelism is easy. The pool may grow or contract in accordance with the workload the jungle is seeing. A testing monkey attempts to execute the task exactly as a new user might, including making reasonable mistakes or assumptions along the way. A second monkey evaluates the attempt to ensure the result wasn’t achieved by implicitly filling in gaps the documentation failed to cover (i.e. this monkey tries to ensure the first didn’t “cheat” at the task). If the second monkey finds a gap, they also suggest a way to fill that gap.</p>

<p>It is worth pausing on what this arrangement actually is. The testing monkey is not standing in for a confused new user as a rhetorical exercise. It is an agent reading documentation in order to accomplish a task, which is increasingly what documentation gets read by. When it fails, it fails for the same reason a person would, which is that the instructions were wrong. The difference is that its failure is legible. The entire attempt is recorded, and a second agent is assigned to determine whether the docs earned the outcome or the first monkey quietly covered for them.</p>

<p>Pemberton takes this reporting and serves it to the jungle in much the way that I would, effectively asking a monkey to do a fix. In all transparancy, I’ve currently injected myself in the middle of this process to be sure I approve her asks, but after about twenty of these requests for monkey resources, I’ve not found anything egregiously wrong and if the monkey doing the work had sent these directly to a pull request, I don’t think I would have been disappointed.</p>

<h2 id="what-mprs-actually-contain">What MPRs actually contain</h2>

<p>It is at this point where we come back to my notion of the MPR and why my disappointment would have been absent if they were autonomously submitted. The fixes that emerge from this process are rarely sweeping changes. They don’t attempt to rewrite sections wholesale or introduce large new narratives. Instead, they target specific points of friction in an exacting way that involved multiple agents performing specific tasks meant to challenge one another in a coordinated fashion. In this way, they surface issues like:</p>

<ul>
  <li>A configuration value that no longer works as written.</li>
  <li>An example that produces different output than what is shown.</li>
  <li>A missing step in a defined process that an experienced user would infer, but a new user would not.</li>
  <li>A statement that was once true, but has since drifted out of alignment with the code.</li>
</ul>

<p>The size of these changes is not something I asked for. No one told the monkeys to keep their diffs small and there is no rule in the jungle capping the lines they are allowed to touch. The size falls out of the detection method. This style of adversarial documentation testing can only surface discrepancies at this grain, so it can only produce corrections at this grain.</p>

<p>That strikes me as the more useful finding. The standing complaint about agent contributions is that the diffs are too large to review, and the usual answers are better review tooling or more discipline in the prompt. This suggests a third option, which is to choose tasks whose findings are small by construction. Reviewability stops being a constraint imposed on the output and becomes a property of how the work was framed.</p>

<p>Individually, then, these MPRs are almost trivial to review. The reviewer can focus on a single, well-defined question: does this correction accurately resolve the discrepancy identified by the test?</p>

<h2 id="merged-examples">Merged examples</h2>

<p>Here are some examples that have merged:</p>

<ul>
  <li><a href="https://github.com/apache/tinkerpop/pull/3533">#3533</a> - <em>Remove stale/incorrect absent-key null-sort claim from order()-step docs</em>
    <ul>
      <li>Detected that the documentation was making a false claim about <code class="language-plaintext highlighter-rouge">order</code> step. This was a remnant of documentation that should have been removed in 2022.</li>
    </ul>
  </li>
  <li><a href="https://github.com/apache/tinkerpop/pull/3542">#3542</a> - <em>Document that asBool() trims whitespace before parsing strings</em>
    <ul>
      <li>Identified semantics that were missing from the <code class="language-plaintext highlighter-rouge">asBool</code> step.</li>
    </ul>
  </li>
  <li><a href="https://github.com/apache/tinkerpop/pull/3543">#3543</a> - <em>Fix inaccurate vertex label description in reference docs</em>
    <ul>
      <li>Found a mistake in how the documentation referred to the actual shape of the sample data in a query example leading to conflict between the example and its explanation.</li>
    </ul>
  </li>
</ul>

<h2 id="why-mprs-hold-value">Why MPRs hold value</h2>

<p>What has surprised me is not just how easy these are to review, but how consistently valuable they are. These are more than cosmetic edits and fix real points of failure in the onboarding experience and troubleshooting. These are the places where someone, or their agent, following the documentation would get stuck, confused, or misled.</p>

<p>In aggregate, they represent <strong>a steady tightening of the contract between documentation and implementation</strong>. This stands in stark contrast to the dominant (and interesting) narrative around agent-generated contributions. Much of the current discussion centers on scale: large diffs, end-to-end features, and the growing burden of reviewing work that no individual developer would reasonably produce in one pass. Those concerns are valid, but they are not the only dimension that matters.</p>

<p>There is also a reason work like this has been hard to sustain, and it is not that nobody cared. Any maintainer or technical writer would correct a stale line in minutes if something pointed them at it. The scarce resource is detection. Documentation drifts one commit at a time, quietly, and finding that drift means re-reading and re-executing material that mostly still works, with no signal indicating which of a thousand documented claims stopped being true last quarter. Code solved this problem with test suites a long time ago, where a broken assertion announces itself. Prose never got that, so verification stayed manual, and manual verification against a moving codebase is bounded by available attention no matter how much anyone cares.</p>

<p>What the monkeys supply is not better judgment than the people who wrote these docs. It is continuous coverage of a surface too large to keep re-reading. The MPR is simply what that coverage looks like when it finds something.</p>

<p>There is also a subtle but important shift in how work is initiated. These pull requests are not the result of a human deciding to improve a particular section of documentation. They are the byproduct of an ongoing, automated effort to verify that what we say matches what actually happens.</p>

<p>That loop, where we test, detect, and correct, runs continuously. Pemberton queues the work, informed by what she already knows, what new changes to the documentation arrive, and what remains untested. The monkeys execute it in isolation. Findings are evaluated and turned into fixes. And without much direct intervention, the system produces a steady flow of small, high-quality contributions. None of this replaces the need for larger, more intentional changes. But it does suggest that there is meaningful value in cultivating this other category of contribution—one that trades size for frequency, and breadth for accuracy.</p>

<h2 id="documentation-as-an-operational-surface">Documentation as an operational surface</h2>

<p>We’ve long thought of documentation as something to be repaired. The testing process quietly assumes something else, which is that documentation is something to be executed.</p>

<p>Consider what <a href="https://github.com/apache/tinkerpop/pull/3533">#3533</a> actually was. The reference docs made a claim about how <code class="language-plaintext highlighter-rouge">order()</code> handled absent keys that had been wrong since 2022. The cost of that error used to be bounded. A person reading it would write a query, get output that did not match the description, and go find out why. The documentation was wrong, but the reader had a feedback loop and a healthy instinct to distrust prose that disagrees with a result on screen. An agent reading that same sentence has neither. It holds no independent belief about how <code class="language-plaintext highlighter-rouge">order()</code> handles absent keys, has no sense that the sentence is four years stale, and feels no pull to go read the source and check. It writes the query, moves on, and the error surfaces somewhere downstream where tracing it back to a line of prose is considerably harder.</p>

<p>That is what <strong>shifts documentation quality from an editorial concern to an operational one</strong>. Stale documentation used to cost a reader some time. It is now an input to systems that will act on it directly, confidently, and at a volume no human readership ever reached.</p>

<h2 id="conclusion">Conclusion</h2>

<p>If the industry is currently grappling with how to absorb massive agent-generated diffs, it may also be worth asking how we can better embrace the opposite extreme in the MPR. While I’ve focused the MPR on documentation, I sense that it has potential for wider applicability for granular, high quality code changes.</p>

<p>But the more durable finding, for me, is that these are two halves of one story. <strong>Agents are on both sides of documentation now</strong>, reading it and repairing it, and the repairs exist only because something is trying to use the docs and failing. The jungle produces a steady flow of small, high quality corrections precisely because it contains a population of readers that cannot skip past a sentence that does not hold. Keeping documentation honest used to be a discipline we asked people to maintain. It is becoming something a system can be arranged to do on its own, which is fortunate, because the cost of not doing it is going up.</p>]]></content><author><name></name></author><category term="snippet" /><summary type="html"><![CDATA[Exploring how an autonomous agent system unexpectedly began producing a steady stream of high-value, low-overhead "Micro Pull Requests" against Apache TinkerPop’s documentation, and what that reveals about documentation quality becoming an operational concern rather than an editorial one.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://stephen.genoprime.com/assets/images/jungle-friends.png" /><media:content medium="image" url="https://stephen.genoprime.com/assets/images/jungle-friends.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Gremlin Knows GQL</title><link href="https://stephen.genoprime.com/snippet/2026/07/27/snippet-26.html" rel="alternate" type="text/html" title="Gremlin Knows GQL" /><published>2026-07-27T00:00:00+00:00</published><updated>2026-07-27T00:00:00+00:00</updated><id>https://stephen.genoprime.com/snippet/2026/07/27/snippet-26</id><content type="html" xml:base="https://stephen.genoprime.com/snippet/2026/07/27/snippet-26.html"><![CDATA[<p><a href="https://tinkerpop.apache.org/gremlin.html">Gremlin</a> has long claimed that it can be both imperative and declarative. It delivered this functionality by way of <code class="language-plaintext highlighter-rouge">match()</code> step which <a href="https://tinkerpop.apache.org/docs/current/reference/#match-stephttps://tinkerpop.apache.org/docs/current/reference/#match-step">accepted anonymous traversals</a> representing graph traversal patterns. While this approach technically worked, most users didn’t find the syntax as easy and intuitive as they would have liked and providers struggled to optimize its functionality. With its limited use cases given those constraints, the step never got much use. For Apache TinkerPop 4, <a href="https://tinkerpop.apache.org/download.html">starting with the 4.0.0-beta.3</a>, the <code class="language-plaintext highlighter-rouge">match()</code> step has been replaced with a more general form that will take a declarative query string. This flexibilty allows providers to offer support for whatever declarative query language they wish to support and offers uses a wider selection of options for writing their queries in the way they wish.</p>

<p>In support of <code class="language-plaintext highlighter-rouge">match()</code> and it’s new design, TinkerPop offers TinkerGQL which is a subset of the <a href="https://www.iso.org/standard/76120.html">GQL ISO standard</a>. It particularly focuses on offering support of the motif-style pattern syntax that describes graph relationships that many find easy to understand. The reference implementation of the processing engine does not translate to Gremlin steps for execution. Instead, it is natively processed in a TinkerGQL engine that has the capability for use by any provider. In this way, virtually any graph can support TinkerGQL as an option. In then end, it is important that you understand the capabilities of the graph database you’re using.</p>

<h2 id="match-and-gql-together">match() and GQL together</h2>

<p>Before we look at the new syntax, let’s start with the old. Here’s a basic use of how <code class="language-plaintext highlighter-rouge">match()</code> formerly worked:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.V().match(__.as("a").hasLabel("person").out("created").hasLabel("software").as("s"),
......1&gt;             __.as("s").hasLabel("software").in("created").hasLabel("person").as("b")).
......2&gt;   where("a", neq("b")).
......3&gt;   select("a", "b", "s").by("name")
==&gt;[a:marko,b:josh,s:lop]
==&gt;[a:marko,b:peter,s:lop]
==&gt;[a:josh,b:marko,s:lop]
==&gt;[a:josh,b:peter,s:lop]
==&gt;[a:peter,b:marko,s:lop]
==&gt;[a:peter,b:josh,s:lop]</code></pre></figure>

<p>With the 4.0.0-beta.3 we can instead use TinkerGQL and do:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.match("MATCH (a:person)-[:created]-&gt;(s:software), (b:person)-[:created]-&gt;(s)").
......1&gt;   where("a", neq("b")).
......2&gt;   select("a", "b", "s").by("name")
==&gt;[a:marko,b:josh,s:lop]
==&gt;[a:marko,b:peter,s:lop]
==&gt;[a:josh,b:marko,s:lop]
==&gt;[a:josh,b:peter,s:lop]
==&gt;[a:peter,b:marko,s:lop]
==&gt;[a:peter,b:josh,s:lop]</code></pre></figure>

<p>The two traversals compute the same result, but they read very differently, with the latter demonstrating some increased readability with GQL allowing for a more direct description of the pattern rather than a Gremlin traversal specifying the pattern.</p>

<p>As you consider the mixed syntax of GQL and Gremlin, note that TinkerGQL does not support <code class="language-plaintext highlighter-rouge">WHERE</code> or <code class="language-plaintext highlighter-rouge">RETURN</code> clauses directly. The focus is on GQLs pattern matching syntax leaving standard Gremlin steps to do additional filtering and transformation. Taking a step back from that more complex example, let’s look at a simpler form to showcase the interface.</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.match("MATCH (p:person)-[:created]-&gt;(s:software)")
==&gt;[s:v[3],p:v[1]]
==&gt;[s:v[3],p:v[4]]
==&gt;[s:v[3],p:v[6]]
==&gt;[s:v[5],p:v[4]]</code></pre></figure>

<p>Basic usage demonstrates that <code class="language-plaintext highlighter-rouge">match()</code> returns a <code class="language-plaintext highlighter-rouge">Map</code> containing all bound variables. From there, you may use normal Gremlin steps to work with that <code class="language-plaintext highlighter-rouge">Map</code>. The following examples show use of <code class="language-plaintext highlighter-rouge">select()</code> as a common pattern for transforming results:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.match("MATCH (p:person)-[:created]-&gt;(s:software)").
......1&gt;   select("p","s").by(elementMap())
==&gt;[p:[id:1,label:person,name:marko,age:29],s:[id:3,label:software,name:lop,lang:java]]
==&gt;[p:[id:4,label:person,name:josh,age:32],s:[id:3,label:software,name:lop,lang:java]]
==&gt;[p:[id:6,label:person,name:peter,age:35],s:[id:3,label:software,name:lop,lang:java]]
==&gt;[p:[id:4,label:person,name:josh,age:32],s:[id:5,label:software,name:ripple,lang:java]]</code></pre></figure>

<p>You could also do aggregations with <code class="language-plaintext highlighter-rouge">group()</code> step:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.match("MATCH (p:person)-[:created]-&gt;(s:software)").
......1&gt;   group().
......2&gt;     by(select("p").bothE().count()).
......3&gt;     by(select("s").values("name"))
==&gt;[1:lop,3:ripple]</code></pre></figure>

<p>The other important pattern to follow transformation would be using <code class="language-plaintext highlighter-rouge">where()</code> for additional filtering. Recall that <code class="language-plaintext highlighter-rouge">where()</code> was designed to work with the original <code class="language-plaintext highlighter-rouge">match()</code> step that took <code class="language-plaintext highlighter-rouge">Traversal</code> arguments and therefore is preferred over <code class="language-plaintext highlighter-rouge">filter()</code> syntatically for that purpose. We saw <code class="language-plaintext highlighter-rouge">where()</code> usage in the first example, but here’s another, written with slightly differently GQL, describing the same query and demonstrating the core pattern for <code class="language-plaintext highlighter-rouge">where()</code> with binding comparison:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.match("MATCH (a:person)-[:created]-&gt;(s:software)&lt;-[:created]-(b:person)").
......1&gt;     where("a", neq("b")).
......2&gt;   select("a", "b", "s").by("name")
==&gt;[a:marko,b:josh,s:lop]
==&gt;[a:marko,b:peter,s:lop]
==&gt;[a:josh,b:marko,s:lop]
==&gt;[a:josh,b:peter,s:lop]
==&gt;[a:peter,b:marko,s:lop]
==&gt;[a:peter,b:josh,s:lop]</code></pre></figure>

<h2 id="match-and-gql-with-air-routes">match() and GQL with Air Routes</h2>

<p>The Air Routes graph is a nice way to show off the syntax and mental model of <code class="language-plaintext highlighter-rouge">match()</code>. Here are some more examples so that you can start to understand the features that TinkerGQL offer within the context of <code class="language-plaintext highlighter-rouge">match()</code>.</p>

<p><strong>Find 3 routes to any airport starting IAD</strong></p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.match("MATCH (a:airport {code: 'IAD'})-[:route]-&gt;(b:airport)").
......1&gt;   limit(3).
......2&gt;   select("a","b").by('code')
==&gt;[a:IAD,b:PBG]
==&gt;[a:IAD,b:YTZ]
==&gt;[a:IAD,b:AOO]</code></pre></figure>

<p><strong>Find routes to any airport starting IAD where the length is exactly 250 miles long</strong></p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.match("MATCH (a:airport {code: 'IAD'})-[r:route {dist: 250}]-&gt;(b:airport)").
......1&gt;   select("a","b","r").
......2&gt;     by("code").by("code").by("dist")
==&gt;[a:IAD,b:ITH,r:250]</code></pre></figure>

<p><strong>Find 3 routes to BOS starting in IAD that require a stop</strong></p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.match("MATCH (a:airport {code: 'IAD'})-[:route]-(b:airport)," +
......1&gt;         "      (b)-[:route]-&gt;(c:airport {code: 'BOS'})").
......2&gt;   limit(3).
......3&gt;   select("a","b","c").
......4&gt;     by("code")
==&gt;[a:IAD,b:PBG,c:BOS]
==&gt;[a:IAD,b:YTZ,c:BOS]
==&gt;[a:IAD,b:YYZ,c:BOS]</code></pre></figure>

<p><strong>Find 3 routes from IAD that have a second leg that is longer than the first</strong></p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.match("MATCH (a:airport {code: 'IAD'})-[r1:route]-(b:airport)," +
......1&gt;         "      (b)-[r2:route]-&gt;(c:airport)").
......2&gt;   where("r1", lt("r2")).by("dist").
......3&gt;   limit(3).
......4&gt;   select("a", "b", "c").by("code")
==&gt;[a:IAD,b:PBG,c:FLL]
==&gt;[a:IAD,b:PBG,c:MCO]
==&gt;[a:IAD,b:PBG,c:MYR]</code></pre></figure>

<p><strong>Find 3 triangle-shaped routes that start and end at IAD</strong></p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.match("MATCH (start:airport {code: 'IAD'})-[:route]-(b:airport)-[:route]-&gt;(c:airport)-[:route]-&gt;(start)"). 
......1&gt;   select("start", "b", "c").by("code").
......2&gt;   limit(3)
==&gt;[start:IAD,b:PBG,c:BOS]
==&gt;[start:IAD,b:PBG,c:MCO]
==&gt;[start:IAD,b:PBG,c:FLL]</code></pre></figure>

<h2 id="on-performance">On Performance</h2>

<p>The performance of <code class="language-plaintext highlighter-rouge">match()</code> directly ties to the capabilities and optimizations of the declarative query language processing engine of the graph database you are using. Speaking specifically for TinkerGQL, used with TinkerGraph and the reference implementation processing engine, early benchmarks demonstrate that there are cases where using <code class="language-plaintext highlighter-rouge">match()</code> is advantageous and that the benefit extends beyond basic query readabilty and convenience.</p>

<p>The best example is for patterns that fullfill similar statistics for “finding airports with routes to ATL”.</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.V().hasLabel("airport").as("a").
......1&gt;   out("route").has("code", "ATL").as("b").
......2&gt;   select("a", "b")
==&gt;[a:v[3],b:v[1]]
==&gt;[a:v[4],b:v[1]]
==&gt;[a:v[5],b:v[1]]
==&gt;[a:v[6],b:v[1]]
==&gt;[a:v[7],b:v[1]]
==&gt;[a:v[8],b:v[1]]
...</code></pre></figure>

<p>If written just as the described by the English description in imperative fashion, we scan all ~3500 airports and then fan out along every route before filtering, paying the full <code class="language-plaintext highlighter-rouge">O(|airports| × degree)</code> cost. Experienced Gremlin users would probably know to invert this query rather than follow the English description:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.V().has("airport", "code", "ATL").as("b").
......1&gt;   in("route").as("a").
......2&gt;   select("a", "b")
==&gt;[a:v[307],b:v[1]]
==&gt;[a:v[437],b:v[1]]
==&gt;[a:v[402],b:v[1]]
==&gt;[a:v[180],b:v[1]]
==&gt;[a:v[363],b:v[1]]
==&gt;[a:v[403],b:v[1]]
...</code></pre></figure>

<p>This change improves the performance of the query as it will take advantage of an index to find “ATL” prior to traversing edges. In the following example, switching to the TinkerGQL form we get to retain the natural representation of the query thereby aligning with the English description. We also don’t need awareness of underlying index concerns or other data statistics.</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.match("MATCH (a:airport)-[:route]-&gt;(b:airport {code: 'ATL'})")
==&gt;[a:v[3],b:v[1]]
==&gt;[a:v[4],b:v[1]]
==&gt;[a:v[5],b:v[1]]
==&gt;[a:v[6],b:v[1]]
==&gt;[a:v[7],b:v[1]]
==&gt;[a:v[8],b:v[1]]
...</code></pre></figure>

<p>This TinkerGQL form outperforms the first imperative query in its natural form by 84x and the manually optimized form by about 12%.</p>

<h2 id="gremlin-and-declarative-query-languages">Gremlin and Declarative Query Languages</h2>

<p>The new capability of <code class="language-plaintext highlighter-rouge">match()</code> step to host declarative query languages, mix them with imperative steps and process them across any TinkerPop-enabled graph system greatly expands the flexibility of the language. It shows how Gremlin can coexist with the future of GQL and augment its capabilty, offering users greater choice in how they express their queries.</p>

<p>While TinkerGQL is still a bit early in its development, there is a great deal of opportunity to expand on the foundations that have been laid. Top of mind are features like variable length path support and the ability to bind Gremlin step labels as seeds to mid-traversal <code class="language-plaintext highlighter-rouge">match()</code> steps. For the latter, imagine a traversal like: <code class="language-plaintext highlighter-rouge">g.V(1).as("a").match("(a)-[:knows]-&gt;(b:person)")</code>. While there is much room for growth with TinkerGQL, we also know that there are TinkerPop providers out there who already have their own native support for other query languages. Consider <a href="https://docs.aws.amazon.com/neptune/latest/userguide/access-graph-opencypher.html">Amazon Neptune with support for openCypher</a>, as it could someday offer access to a mixed execution engine that would give you openCypher and Gremlin together.</p>

<p>This new offering with <code class="language-plaintext highlighter-rouge">match()</code> opens a great many doors for exploration and growth in TinkerPop 4.0 for both its developers, its providers and its users. It will be both exciting and interestings to see how this feature expands and how it is used.</p>]]></content><author><name></name></author><category term="snippet" /><summary type="html"><![CDATA[Gremlin’s revised `match()` step better supports the notion of Gremlin being both an imperative and declarative query language and with GQL support out-of-the box demonstrates the relationship between Gremlin and the ISO GQL standard.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://stephen.genoprime.com/assets/images/gremlin-knows-gql.png" /><media:content medium="image" url="https://stephen.genoprime.com/assets/images/gremlin-knows-gql.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Graphs, Agents, and the Characters Between</title><link href="https://stephen.genoprime.com/snippet/2026/06/01/snippet-25.html" rel="alternate" type="text/html" title="Graphs, Agents, and the Characters Between" /><published>2026-06-01T00:00:00+00:00</published><updated>2026-06-01T00:00:00+00:00</updated><id>https://stephen.genoprime.com/snippet/2026/06/01/snippet-25</id><content type="html" xml:base="https://stephen.genoprime.com/snippet/2026/06/01/snippet-25.html"><![CDATA[<p>If you’re around folks who have used <a href="https://tinkerpop.apache.org/gremlin.html">Gremlin</a> as their graph query language long enough, I think there is a tendency toward personifying him a bit. Gremlin is as much the query as he is the actor who walks around a graph collecting your data. In explaining Gremlin to folks, it’s not uncommon for me to find myself asking people to envision Gremlin walking from one vertex to another. I find the imagery of Gremlin and all his friends incredibly helpful in describing the occasional complexities of graphs and <a href="https://tinkerpop.apache.org/">Apache TinkerPop</a>.</p>

<p>I think it is for this reason I’ve enjoyed working with <a href="https://gastownhall.ai/">Gastown</a>. While TinkerPop has Gremlin and robot friends to describe their graph world, Gastown has a Mayor, Polecats, Refineries and other characters to help describe multi-agent orchestration. And, for my own cases where Gastown doesn’t quite fit, I have my own personal agent orchestration system formulated around imagery of a jungle full of Monkeys, Coconuts, a Toucan and a patient Capybara.</p>

<p>None of this is just branding.</p>

<p>The more moving pieces a system has, the more we lean on metaphor to keep it all straight in our heads. At some point the  diagrams and generic names for components and systems fail to convey a form that is easy or fun to think about, and you end up talking about “friends” instead: the one who walks the graph, the one who schedules the work, the one who watches for trouble. The names we give those friends end up being the real user interface.</p>

<h1 id="the-tinkerpop-cast-as-cognitive-api">The TinkerPop cast as cognitive API</h1>

<p>In TinkerPop, we talk about Gremlin as if it were a character, not just a query language. Gremlin wanders the graph, carries state, makes decisions, and brings back results. Gremlin’s canine robot friend, Rexster, listens for requests for information on the graph and obediantly fetches you results as a good robot dog would. Furnace burns hot with fire as he processes complex graph alogrithms and performs other analytics. The graph itself becomes a kind of world, The TinkerPop, that they inhabit. The traversal machine turns into the physics of that world, quietly enforcing the rules under which they live their little lives.</p>

<p>Individually, none of these characters is technically necessary. You can explain everything with common terms like “vertices, edges, traversers, execution engines, drivers and servers.” But in practice, people latch onto the characters and visualize their connection to the system. It helps orient you and reduces iterface friction with the underlying tool. You end up with a mental model you can actually carry around.</p>

<h1 id="gastowns-civic-metaphor-for-multiagent-systems">Gastown’s civic metaphor for multi‑agent systems</h1>

<p>The same thing is happening in the new wave of multi‑agent systems, and Gastown is a particularly explicit example. Gastown is “a workspace for coordinating multiple AI coding agents over git‑backed projects.” That is accurate description but also matches the description of other such projects.</p>

<p>The metaphor is where it comes alive and makes it memorable. Instead of “orchestrator,” you get a <strong>Mayor</strong>. The Mayor doesn’t typically write code; they talk to you, breaks your request into work units, and assigns them. It is the character who knows what’s going on, keeps the big picture in mind, and tells other folks what to do. Instead of “ephemeral worker processes,” you get <strong>Polecats</strong>. Polecats are the hands‑on coders who take on tasks, touch the files, run tools, and propose changes. The Mayor calls them up when it needs something done. Instead of “git‑backed state” and “issue abstraction,” you get <strong>Refineries</strong> and <strong>Beads</strong>. Work is encapsulated in Beads, which are small units associated with code changes, issues, or tasks—that flow through a Refinery which is a merge queue processor. Together with other actors and entities, Gastown logically makes intuitive sense.</p>

<p>Once you have that cast, you don’t have to remember how all the internal components talk to each other. You just say, “I’ll ask the Mayor to spin up a few Polecats.” The details are still there, but you only pull them out when you need them.</p>

<h1 id="a-jungle-of-tasks-coconuts-and-monkeys">A jungle of tasks, Coconuts, and Monkeys</h1>

<p>Gastown’s metaphors are tuned for a multi‑agent coding town, but it’s opinionated approach doesn’t always fit what I’m working on. I found that I needed my own metaphor for a multi-agent system. My own mental model for agent orchestration looks less like a small industrial city and more like a dense, noisy, surprisingly well‑organized jungle.</p>

<p>I spend most of my time in a <strong>Hammock</strong> strung between two trees. The Hammock is the thinking spot. It’s where I can see the broad outlines of the jungle which encompasess the cross-sectionality of things I might be working on. From there, I think through ideas, decide what should happen next, and keep an eye on the overall ecosystem.</p>

<p>Ideas and tasks arrive in the Hammock first. Some are half‑formed, some are clearly work. When one is ready to leave my head and become something an agent can work on, it goes into a <strong>Coconut</strong>.</p>

<p>Coconuts are the basic unit of work in the jungle. They are durable. They can sit by the Hammock while I’m still getting my thoughts straight. They can be set aside and later cracked open to be filled with more detail or context. A Coconut might represent a bug, an experiment, a whole feature, or a piece of documentation I want to have.</p>

<p>Once a Coconut is ready I roll it out into the jungle and the <strong>Monkeys</strong> take notice. The jungle is full of Monkeys I’ve trained in specific skills. Some know how to write documentation, while others are experts at writing code, creating tests or are any number of other tasks. When a Monkey spots a Coconut that matches its training, it swings down, picks it up, and starts working on it. That Monkey is also smart enough to know when it needs a team filled with other expertise and will recruit other Monkeys with the right skills to help it out. By this point, however, I’ve moved on in my Hammock to the next Coconut.</p>

<p>When the Monkey is done he bring the results back to the Hammock. Other times, the Monkey realizes it’s in over its head and calls for help. I can either interact with it by shouting from my Hammock or meet up with it one-on-one for more direct, focused work.</p>

<p>From my perspective in the Hammock, I can always look out and see what the Monkeys are doing. I can see which Coconuts are being held, which ones are still lying in the leaves, and which ones are making their way back. If a Monkey has been sitting with the same Coconut for too long, I can swing down myself, take a look, and either give it a nudge or pull the Coconut back to the Hammock for rethinking.</p>

<p>In the background, a <strong>Capybara</strong> patrols the edges of the jungle and watches the health of the ecosystem. It lets me know if something systemic is wrong, like abandoned Coconuts and lost messages from the Monkeys. I can also lean on a <strong>Toucan</strong> for investigating when something is wrong in the jungle and count on him to fix it so that it doesn’t happen again.</p>

<p>This lightweight jungle metaphor for managing agents, inspired by Gastown, has helped me be incredibly productive. I find it so natural to say, “Let’s get a monkey to work on JIRA-55674” or “How far along is Bobo right now in fixing the bug?” or “What’s been happening in the jungle since I left yesterday?” It’s also made the devilry of agents sometimes comical. I once had a Monkey named Jinx get extremely confused. She went on a destructive tear, deleting a great many workspaces of other Monkeys who were actively trying to work. Jinx. How perfect a name.</p>

<h1 id="the-power-and-risk-of-friendly-metaphors">The power and risk of friendly metaphors</h1>

<p>A good metaphor compresses down all the edge cases and error states into something you can naturally recall and interact with as a model seamlessly. You don’t have to remember exactly how a traverser carries its state if you can remember what a Gremlin does. You don’t need to rehearse Gastown’s internal APIs if you can talk about what the Mayor and Polecats are up to. You can keep your own agent setup in your head if all you have to remember is “Coconuts roll into the jungle, trained Monkeys grab them, and the Capybara complains when they don’t come back.”</p>

<p>Metaphors also make it easier to teach and to debug. When a newcomer asks where something should live in a graph application, it is easier to say, “That’s a job for this character” than to throw a set of technical terms at them. When something goes wrong, it helps to be able to say, “The Mayor is assigning too much work to this one Polecat,” or “We’ve trained the wrong Monkeys for this kind of Coconut,” and have everyone instantly know what that means.</p>

<p>On the other hand, cute metaphors can make serious systems feel lighter than they are. For example, a Monkey dropping a Coconut means loss of real work. Metaphors can also lock in a certain worldview. If you only ever think in terms of individual characters, you might miss the fact that the system is really a swarm. If your metaphor is too rigid, it will resist architectural changes you need to make later.</p>

<p>But on balance, I think it is worth being deliberate about the stories we tell around our systems. If you are going to be living with a complex graph stack, a multi‑agent workspace, or your own cluster of personal tools, you might as well give yourself a cast of characters you actually enjoy spending time with. The code will do what it does either way. The metaphor is for you.</p>]]></content><author><name></name></author><category term="snippet" /><summary type="html"><![CDATA[Using character‑driven metaphors has long helped shape the way people think about Apache TinkerPop and graphs, but this same approach equally helps with other complex systems, like multi‑agent workflows.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://stephen.genoprime.com/assets/images/gremlin-gastown-jungle.png" /><media:content medium="image" url="https://stephen.genoprime.com/assets/images/gremlin-gastown-jungle.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Long-term agentic memory in Apache TinkerPop using Beads</title><link href="https://stephen.genoprime.com/snippet/2026/04/27/snippet-24.html" rel="alternate" type="text/html" title="Long-term agentic memory in Apache TinkerPop using Beads" /><published>2026-04-27T00:00:00+00:00</published><updated>2026-04-27T00:00:00+00:00</updated><id>https://stephen.genoprime.com/snippet/2026/04/27/snippet-24</id><content type="html" xml:base="https://stephen.genoprime.com/snippet/2026/04/27/snippet-24.html"><![CDATA[<p>In my last post, <a href="/snippet/2026/04/03/snippet-23.html">Gremlin goes to Gastown</a>, I spent some time on how <a href="https://github.com/gastownhall/beads">Beads</a> shapes and links tasks to help drive the execution side of agentic workflows. There is a lot of thinking from human and AI that lead up to that execution where we get a final, working piece of code as an output. I belive that thinking-part, that ledger of choice, is an interesting artifact in and of itself and for the most part, it is unfortunately lost in the process. This post explores how Beads helps maintain that artifact, thereby providing a long-term memory for agents.</p>

<p>When working with an agent, development becomes a conversation. There’s a steady back-and-forth where decisions get made in different ways. Sometimes the human is explicit. Sometimes the agent fills in gaps. Sometimes both converge on something without ever really stating it outright. By the time code is written, a lot has already happened. What gets committed at the end of that process, however, looks pretty familiar with source code, tests, maybe some documentation all finding their way to a Git repository. We’d think of these things as the usual artifacts we’ve always produced and what mattered. The conversation and thinking that produced those artifacts, such as the reasoning, the trade-offs, and the abandoned directions mostly disappear.</p>

<p>That’s not a new problem. It’s how software development has generally worked. Most of that decision-making has historically lived in someone’s head, with only fragments making their way into comments or design documentation. The difference now is that, with agents, that thinking actually exists in a concrete form. It’s written down, but just isn’t preserved in a way that’s particularly useful. You could try to keep the full transcript, but that quickly becomes unwieldy. A raw session log is dense, noisy, and difficult to navigate. It’s not something you can reasonably query or expect an agent or human to make effective use of later. Storing it verbatim doesn’t really solve the problem; it just changes where the problem lives.</p>

<p>What seems more promising is to treat that stream of decisions as something that can be structured. This is where Beads starts to feel like more than just a task coordination mechanism or issue tracker.</p>

<p>A bead already represents a unit of work, but it also carries relationships describing what it depends on, what it blocks, and where it fits in a larger effort. That structure is a graph, and that graph is already capturing part of the story. The missing piece is the reasoning that led to the bead itself.</p>

<p>Consider the following bead from <a href="https://tinkerpop.apache.org/">Apache TinkerPop</a> contributor, <a href="https://github.com/Cole-Greer">Cole Greer</a>:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ bd show tinkerpop-big.11
○ tinkerpop-big.11 · Multi-Label Vertex Implications for Schema   [● P2 · OPEN]
Owner: Cole-Greer · Type: task
Created: 2026-04-02 · Updated: 2026-04-02

DESCRIPTION
Investigate and address implications of multi-label vertices for the schema system.                 
                                                                                                    
Questions to Resolve                                                                                
Some providers support vertices with multiple labels. If a vertex has labels "person" and "employee",
what does type() return? Both VertexType vertices?                                                  
Should VertexType model single labels or label-sets?                                                
How do property definitions compose when a vertex matches multiple types?                           
Does schema enforcement (bead 7) need to validate against all matching types or just one?           
Should the schema system remain label-based (matching TinkerGraph's single-label model) with multi- 
label as a provider extension, or should it be first-class?                                         
                                                                                                    
Notes                                                                                               
TinkerGraph only supports single-label vertices, so the reference implementation won't exercise this
This may only need a design decision and documentation rather than code changes, depending on the   
outcome                                                                                             


PARENT
  ↑ ○ tinkerpop-big: (EPIC) Graph Schema Interfaces ● P1

DEPENDS ON
  → ○ tinkerpop-big.1: Core Schema Interfaces (gremlin-core) ● P1
</code></pre></div></div>

<p>This bead is a bit different. It doesn’t describe a concrete implementation step so much as it captures a set of unresolved questions. It’s essentially a snapshot of uncertainty. You can see the shape of the problem immediately. Multi-label vertices introduce ambiguity into a model that has historically assumed a single label. From there, the questions start to branch. What does <code class="language-plaintext highlighter-rouge">type()</code> mean in that world? Is a type still tied to a single label, or does it become something compositional? If multiple types apply, how do their properties interact? Even the scope of the work is unclear—this might turn into code, or it might resolve as documentation.</p>

<p>What’s interesting is that this bead already contains more of the “thinking” than a typical task. It exposes the open edges of the design space, but it still stops short of capturing how those questions eventually get resolved. At some point, decisions will be made. The TinkerPop Community will come to consensus on one model over another, certain trade-offs will be accepted, and some paths outright rejected. When that happens, the bead will likely be updated, maybe closed, and the resulting changes will show up in code and docs. The path from these questions to those decisions is where most of the insight lives, and will be found in future connected beads when they are made. The character of the Beads graph moves from just being a dependency tracker to look more like a memory system.</p>

<p>In that model, a bead is no longer just “something to do” or even “something that was done.” It becomes an anchor point for a set of decisions. Those decisions can branch, reference each other, and carry context forward. Over time, the graph accumulates not just the history of changes, but the reasoning behind them, offering interesting implications for both humans and agents.</p>

<p>For a human coming back to a piece of code months later, the usual question is “why is this like this?” The answer is rarely obvious from the code itself. With a graph of decisions attached, that question becomes something you can actually traverse.</p>

<p>For an agent, the impact is probably even more significant. Instead of inferring intent from the current state of the code, it can follow the path of decisions that led there. Constraints, prior trade-offs, even rejected approaches become part of the available context. That starts to look a lot less like stateless prompting and a lot more like memory.</p>

<p>The important shift here is in what we consider part of the deliverable. Right now, the session is treated as disposable. The code is the artifact that matters, and everything else is intermediate. But if the session contains the reasoning that produced the code, then throwing it away means discarding part of the work. With Beads already providing a graph at the center of the codebase extending that graph to include decisions feels like a natural progression rather than a separate system.</p>

<p>Viewed that way, Beads starts to take on a different role. It isn’t just coordinating work across agents. It’s accumulating the memory of how that work came to be. I find it interesting and, yet unsurprising, that the intersection of beads, memory, decision-making and other points of this post all culminate in a graph. Perhaps, TinkerPop and <a href="https://tinkerpop.apache.org/gremlin.html">Gremlin</a> will someday play a role in navigating a Beads graph to help guide its own development.</p>]]></content><author><name></name></author><category term="snippet" /><summary type="html"><![CDATA[Using Beads, a memory upgrade for your coding agent, to capture a new graph-based artifact in agentic coding for Apache TinkerPop.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://stephen.genoprime.com/assets/images/gremlin-gastown-beads.png" /><media:content medium="image" url="https://stephen.genoprime.com/assets/images/gremlin-gastown-beads.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Gremlin goes to Gastown</title><link href="https://stephen.genoprime.com/snippet/2026/04/03/snippet-23.html" rel="alternate" type="text/html" title="Gremlin goes to Gastown" /><published>2026-04-03T00:00:00+00:00</published><updated>2026-04-03T00:00:00+00:00</updated><id>https://stephen.genoprime.com/snippet/2026/04/03/snippet-23</id><content type="html" xml:base="https://stephen.genoprime.com/snippet/2026/04/03/snippet-23.html"><![CDATA[<p>For some months now, I’ve been reading about ways to scale my usage of AI coding agents like <a href="https://kiro.dev/">Kiro</a> and <a href="https://claude.com/product/claude-code">Claude Code</a> while also seeking greater efficiencies in their operations in terms of the time taken to produce their output. I’ve kept finding myself drawn more and more to <a href="https://github.com/gastownhall/gastown">Gastown</a>, a multi-agent workspace manager. I decided to try a small experiment to get a feel for how development with it compares to a standard coding agent session and, in that experiment, bring <a href="https://tinkerpop.apache.org/gremlin.html">Gremlin</a> development into Gastown for a bit to see what I could successfully build.</p>

<h2 id="why-gastown-and-why-gremlator">Why Gastown, and why Gremlator?</h2>

<p>Since learning about Gastown around the time of its <a href="https://steve-yegge.medium.com/welcome-to-gas-town-4f25ee16dd04">announcement</a> at the start of this year, I’ve been quietly following and picking through the documentation. In some ways, its use of personas like deacons, polecats and mayors to represent elements of its ecosystem reminded me of TinkerPop, with its characters like Gremlin, Rexster, and Blueprints, that each helped you visualize some component of a complex system making it a bit easier to learn. The fun characters aside, I was attracted to what it offered conceptually: an opinionated way to turn “a bunch of coding agents” into a coordinated, auditable workflow where planning, execution, and attribution are all first-class data.</p>

<p>I’m further fascinated by its use of <a href="https://github.com/gastownhall/beads">Beads</a> as a means for providing memory to coding agents. I tend to think that Beads as a standalone tool could be extremely useful in providing better structure to agents given its use of a dependency-aware graph for driving operations as opposed to just markdown text.</p>

<p><a href="https://www.gremlator.com/">Gremlator</a> was a good test case. TinkerPop already has a Gremlator web app that lets you translate Gremlin between languages, but the original implementation was a Java/JavaScript hybrid: the frontend talked to Java <code class="language-plaintext highlighter-rouge">Translator</code> classes behind the scenes, which required a server. Now that we have corresponding translators implemented in <code class="language-plaintext highlighter-rouge">gremlin-javascript</code> for 4.0.0-beta.2, it should be possible to rebuild Gremlator as a pure JavaScript app using the same React/Webpack infrastructure that already powers <a href="https://gremlint.com">Gremlint</a>.</p>

<p>That combination of non-trivial feature work, a concrete before/after architecture, and a real codebase made Gremlator a good choice for getting Gremlin into Gastown.</p>

<h2 id="comparing-the-plans">Comparing the plans</h2>

<p>In my comparison, I used essentially the same kickoff prompt twice: once through Gastown’s mayor, and once in a plain Claude session. While I use Kiro quite extensively, I chose Claude since it works out-of-the-box with Gastown and wanted to use the same tool. Gastown naturally “thinks” in Beads and I asked my standalone Claude session to do the same. In both cases, I received a Beads-style dependency graph and a gated work plan for rebuilding Gremlator as a pure JavaScript app.</p>

<p>What’s striking is how similar the two resulting graphs were. Both decomposed the work into roughly the same backbone:</p>

<ul>
  <li>Scaffold a new project and basic app shell.</li>
  <li>Wire up the gremlin-javascript translators and generation prerequisites.</li>
  <li>Build out the store, input, layout, tabs, and alert components.</li>
  <li>Implement the translation logic and main view.</li>
  <li>Finish with build integration and documentation.</li>
</ul>

<p>Each plan also introduced gates in similar places: an initial gate for project skeletons and generation scripts, a big parallel fan-out for UI and state components, then a single-agent integration gate before build and docs. In other words, given the same description of the problem, both “town” and “single agent” converged on almost the same graph.</p>

<p>The differences are mostly about how you’re meant to run that plan. The Gastown graph is written in the language of its ecosystem: Beads refer to agent owners, gates help control workflows, and assignments that assume mayors and polecats will carry out the work. The Claude-only graph talks about “single agent” versus “three agents in parallel,” but those are just abstract ideas in prose that may or may not carry out as such without your supervision.</p>

<p>There’s also a difference in tempo. Gastown produced its graph in under ten minutes, while the single Claude session took on the order of thirty minutes of consideration to reach a similar place. In addition, Gastown did not need the same level of back-and-forth prompting as Claude did to produce the same plan. I’ve not been able to confirm if this speed difference has anything to do with Gastown itself or not.</p>

<p>So at the planning level, the experiment didn’t show that Gastown finds some completely different structure for the work. It showed that it can get to a town-shaped version of the same plan faster, with more of the execution details and role assumptions embedded in the Beads, whereas a single Claude chat gives you a similar graph but leaves orchestration and discipline up to you.</p>

<h2 id="what-i-learned-from-the-comparison">What I learned from the comparison</h2>

<p>In reflecting on my experiment, I think Gastown stood out in the following ways:</p>

<ul>
  <li><strong>Faster, richer planning.</strong> With essentially the same prompt, Gastown produced a detailed, executable Bead graph in about a third of the time.</li>
  <li><strong>Native orchestration.</strong> The gates/polecats/mayor setup maps directly onto how work is actually scheduled and executed, instead of living as a suggestion in a markdown document.</li>
  <li><strong>Persistent design memory.</strong> Native Beads usage backed by the <a href="https://www.dolthub.com/">Dolt</a> version controlled database, appear to provide a good base for a long-term project memory that will allow recall of fine-grained implementation decisions.</li>
</ul>

<p>On the other hand, Gastown also had me considering:</p>

<ul>
  <li><strong>Idle burn.</strong> A “live” town is like a running cluster in that it is doing things even when you’re not actively watching, and your credit bill reflects that.</li>
  <li><strong>Complexity overhead.</strong> You trade a simple “me and my agent” relationship for something with many moving parts that can operate in ways that feel opaque when you’re getting started.</li>
  <li><strong>Moving target factor.</strong> Gastown is a young, fast-moving project where features and conventions are continuously evolving, so you may need to be ready to handle some sharp edges.</li>
</ul>

<h2 id="where-this-is-going-next">Where this is going next</h2>

<p>This Gremlator experiment was deliberately modest. Gastown used its plan to generate Gremlator in a few minutes with only some minor intervention at the end where it didn’t have a deployment script quite right. That feature will be part of the next 4.0.0 release (the next beta or the official version, whichever comes first). The experience was enough to convince me that Gastown (and Beads itself) are definitely worth further investigation.</p>]]></content><author><name></name></author><category term="snippet" /><summary type="html"><![CDATA[Using Gastown, a multi-agent workspace manager, to build Gremlator for Apache TinkerPop.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://stephen.genoprime.com/assets/images/gremlin-goes-to-gastown.png" /><media:content medium="image" url="https://stephen.genoprime.com/assets/images/gremlin-goes-to-gastown.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">TinkerPop 3.8.0 Reflections</title><link href="https://stephen.genoprime.com/snippet/2025/11/14/snippet-22.html" rel="alternate" type="text/html" title="TinkerPop 3.8.0 Reflections" /><published>2025-11-14T00:00:00+00:00</published><updated>2025-11-14T00:00:00+00:00</updated><id>https://stephen.genoprime.com/snippet/2025/11/14/snippet-22</id><content type="html" xml:base="https://stephen.genoprime.com/snippet/2025/11/14/snippet-22.html"><![CDATA[<p><a href="https://tinkerpop.apache.org/">Apache TinkerPop</a> recently announced the joint releases of 3.7.5 and 3.8.0. I think that makes the total number of releases of 3.x under the <a href="https://www.apache.org/">Apache Software Foundation</a> to be around 75 since 2015. If you follow TinkerPop then you know that the versioning scheme has been such that we allow breaking changes along minor versions and that the major version is a bit more symbolic than a sticking point of semantic versioning. So, while it seems as though TinkerPop has largely just been in a maintenance mode for 3.x for a decade, there’s actually been a great many new features and improvements that have landed along the way in various releases.</p>

<ul>
  <li>The 3.5.x line, “The Sleeping Gremlin: No. 18 Entr’acte Symphonique”, introduced <a href="https://tinkerpop.apache.org/docs/current/upgrade/#_transaction_improvements">remote transactions</a> with <code class="language-plaintext highlighter-rouge">g.tx()</code> and <code class="language-plaintext highlighter-rouge">gremlin-go</code>.</li>
  <li>The 3.6.x line, “Tinkerheart”, added <a href="https://tinkerpop.apache.org/docs/current/upgrade/#_mergev_and_mergee"><code class="language-plaintext highlighter-rouge">mergeV</code> and <code class="language-plaintext highlighter-rouge">mergeE</code></a> for upsert patterns, which drastically simplified Gremlin traversals and made the hard part of loading data more approachable.</li>
  <li>The 3.7.x line, “Gremfir Master of the Pan Flute”, focused on adding Gremlin syntax offering primitive operations around manipulation of <a href="https://tinkerpop.apache.org/docs/current/upgrade/#_string_manipulation_steps">strings</a>, <a href="https://tinkerpop.apache.org/docs/current/upgrade/#_date_manipulation_steps">dates</a>, and <a href="https://tinkerpop.apache.org/docs/current/upgrade/#_list_manipulation_steps">lists</a>, creating the largest expansion of the Gremlin language since the 3.x line began. It also introduced basic <a href="https://tinkerpop.apache.org/docs/3.8.0-SNAPSHOT/upgrade/#_tinkergraph_transactions">transactions to TinkerGraph</a> and made Gremlin Language Variants more first class citizens by offering a way to return <a href="https://tinkerpop.apache.org/docs/current/upgrade/#_properties_on_elements">properties on elements</a>.</li>
</ul>

<p>The 3.8.0, <a href="https://www.youtube.com/shorts/RBeKkcJhyKo">“Grix Greven”</a>, release has a slightly different story. In a sense, it was not contemplated to be as big as it came to be. Version 4.0.0 was on the horizon as a large breaking change, where TinkerPop would add major new features but, also address many inconsistencies and problems that could only be made in a version change where major incompatibilities could be taken. In the midst of that work, 4.0.0 was feeling like a cliff with a steep drop-off given all that was planned. To try to lessen that impact for users, we opted to an intermediate release of 3.8.0 that would focus on fixes to Gremlin semantics while 4.0.0 would focus on API and infrastructural changes.</p>

<p>In essence, 3.8.0 and 4.0.0 would carry the same exact Gremlin semantics, but you could expect driver and API incompatibility in 4.0.0. With this approach, those using 3.x wouldn’t be locked out of neat Gremlin features and the upgrade path to 3.8.x could focus strictly on Gremlin issues. When it was time to go to 4.x, users would know that coming from 3.8.x their Gremlin would have no behavioral issues and would only have to focus on infrastructural and API modifications. Ideally, those modifications would only be in driver configurations and resolving small, easily identifiable compile errors.</p>

<p>Ultimately, this strategy has kept development well focused within 3.8.0. While there are an extensive number of <a href="https://tinkerpop.apache.org/docs/3.8.0/upgrade/#_tinkerpop_3_8_0_2">breaking changes</a>, they come with the benefit of clear query semantics that are more readily optimizable by your favorite graph databases. While this upgrade may be more complex than most, it will be well worth the effort.</p>

<p>It’s hard to think about 3.8.0 without considering the impact of AI in the last couple of years. As I consider the earliest of those 75 or so releases, I don’t think we could have contemplated the tools we have at our disposal today for development. The 3.8.0 release made an important step to better connect TinkerPop to those tools with the introduction of a <a href="https://www.npmjs.com/package/gremlin-mcp">Gremlin MCP Server</a>. While it is still just an alpha release, it offers some interesting features and positions TinkerPop to expand further in this area. It also offers something new in its Upgrade Documentation, providing a <a href="https://tinkerpop.apache.org/docs/3.8.0/upgrade/#_ai_based_risk_assessment">pre-packaged prompt</a>) for AI-based coding agents that will help provide a risk assessment for upgrading an existing code base. This should help you better understand the tasks you will encounter in the upgrade process and allow you to plan your efforts accordingly.</p>

<p>The TinkerPop Community decided some years ago that it would deviate from its symbolic versioning system and move to a semantic versioning style that is more clearly understood. As a result, it is unlikely that we will ever again see 75 releases on the same major release line. It’s more likely TinkerPop 4.x, 5.x, and 6.x will come more rapidly. Having personally watched 3.x go by for ten years, it will be an interesting change in policy to get used to. I’m looking forward to the tail end of the this 3.x era with 3.8.0, as well as the next stage of development that the TinkerPop Community brings with 4.0.0.</p>]]></content><author><name></name></author><category term="snippet" /><summary type="html"><![CDATA[Reflections on TinkerPop 3.8.0’s release strategy, bridging stable Gremlin semantics with future-focused upgrades.]]></summary></entry><entry><title type="html">Semantics of times(0)</title><link href="https://stephen.genoprime.com/snippet/2025/08/21/snippet-21.html" rel="alternate" type="text/html" title="Semantics of times(0)" /><published>2025-08-21T00:00:00+00:00</published><updated>2025-08-21T00:00:00+00:00</updated><id>https://stephen.genoprime.com/snippet/2025/08/21/snippet-21</id><content type="html" xml:base="https://stephen.genoprime.com/snippet/2025/08/21/snippet-21.html"><![CDATA[<p>The <code class="language-plaintext highlighter-rouge">repeat()</code> step in Gremlin has some noteworthy behavior when used with <code class="language-plaintext highlighter-rouge">times(0)</code>. Most of us intuitively expect that <code class="language-plaintext highlighter-rouge">times(1)</code> means “do it once” and <code class="language-plaintext highlighter-rouge">times(0)</code> means “skip it completely.” But depending on <em>where</em> you specify <code class="language-plaintext highlighter-rouge">times()</code>, the semantics are not quite what you might first imagine.</p>

<p>Consider the following Gremlin Console session:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">gremlin&gt; g.V().repeat(out().limit(1)).times(1)
==&gt;v[3]
gremlin&gt; g.V().repeat(out().limit(1)).times(0)
==&gt;v[3]
gremlin&gt; g.V().times(1).repeat(out().limit(1))
==&gt;v[3]
gremlin&gt; g.V().times(0).repeat(out().limit(1))
==&gt;v[1]
==&gt;v[2]
==&gt;v[3]
==&gt;v[4]
==&gt;v[5]
==&gt;v[6]</code></pre></figure>

<p>At first glance, <code class="language-plaintext highlighter-rouge">times(1)</code> behaves exactly as expected in both positions: the traversal applies the repeat once. No surprises there.</p>

<p>Where things get interesting is with <code class="language-plaintext highlighter-rouge">times(0)</code>:</p>

<ul>
  <li>
    <p><strong>With <code class="language-plaintext highlighter-rouge">repeat(...).times(0)</code></strong> - You get the same result as <code class="language-plaintext highlighter-rouge">times(1)</code>. This is because when <code class="language-plaintext highlighter-rouge">times()</code> is applied <em>after</em> <code class="language-plaintext highlighter-rouge">repeat()</code>, its semantics are handled like a <code class="language-plaintext highlighter-rouge">do/while</code>. That is, the <code class="language-plaintext highlighter-rouge">repeat()</code> always executes once before the “how many times?” condition is enforced. So even though you asked for “0 times,” the traversal still enters the <code class="language-plaintext highlighter-rouge">repeat()</code> a first time.</p>
  </li>
  <li>
    <p><strong>With <code class="language-plaintext highlighter-rouge">times(0).repeat(...)</code></strong> – The behavior flips. Here the traversal sees the <code class="language-plaintext highlighter-rouge">times(0)</code> before entering the repeat, giving it <code class="language-plaintext highlighter-rouge">while/do</code> semantics instead. Since the condition is “zero times,” the traverser never enters <code class="language-plaintext highlighter-rouge">repeat()</code>. Instead, it simply passes through unchanged. That’s why, in this case, you just get the original set of vertices back.</p>
  </li>
</ul>

<p>So the placement of <code class="language-plaintext highlighter-rouge">times()</code> fundamentally changes the control flow:</p>

<ul>
  <li><strong>Postfix (<code class="language-plaintext highlighter-rouge">repeat(...).times(n)</code>)</strong> - <code class="language-plaintext highlighter-rouge">do/while</code> semantics (always one iteration, then check).</li>
  <li><strong>Prefix (<code class="language-plaintext highlighter-rouge">times(n).repeat(...)</code>)</strong> - <code class="language-plaintext highlighter-rouge">while/do</code> semantics (check first, then maybe iterate).</li>
</ul>

<p>This quirk in Gremlin’s semantics isn’t a bug, but it can be surprising to discover that sometimes <code class="language-plaintext highlighter-rouge">times(0)</code> doesn’t actually mean “zero.”</p>]]></content><author><name></name></author><category term="snippet" /><summary type="html"><![CDATA[Unpacks subtle differences in Gremlin’s repeat step when `times(0)` is used]]></summary></entry><entry><title type="html">constant() is Not inject() – A Follow-Up</title><link href="https://stephen.genoprime.com/snippet/2025/08/15/snippet-20.html" rel="alternate" type="text/html" title="constant() is Not inject() – A Follow-Up" /><published>2025-08-15T00:00:00+00:00</published><updated>2025-08-15T00:00:00+00:00</updated><id>https://stephen.genoprime.com/snippet/2025/08/15/snippet-20</id><content type="html" xml:base="https://stephen.genoprime.com/snippet/2025/08/15/snippet-20.html"><![CDATA[<h2 id="inject-and-constant-revisited">inject() and constant() Revisited</h2>

<p>In my previous blog post, <a href="https://stephen.genoprime.com/snippet/2020/02/15/snippet-2.html">“constant() Is Not inject()”</a>, I explored the functional and conceptual differences between Gremlin’s <code class="language-plaintext highlighter-rouge">constant()</code> and <code class="language-plaintext highlighter-rouge">inject()</code> steps. At first glance, they both appear to simply stick new values into a traversal, but we saw that their true behaviors are quite distinct.</p>

<p>Since then, a new use case involving <code class="language-plaintext highlighter-rouge">addV</code> has come up that further underscores just how differently these two steps operate, especially when you try to use them in places you might not expect.</p>

<h2 id="addv-scenarios">addV Scenarios</h2>

<p>Suppose you want to add a vertex with a dynamic label via a traversal. You might be tempted to use <code class="language-plaintext highlighter-rouge">inject()</code> to push that label into your stream, but you’ll quickly find the outcome is not what you expect.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gremlin&gt; g.addV(__.inject('x'))
class java.lang.Boolean cannot be cast to class java.lang.String (java.lang.Boolean and java.lang.String are in module java.base of loader 'bootstrap')
Type ':help' or ':h' for help.
Display stack trace? [yN]
</code></pre></div></div>

<p>Instead, you’d likely want:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>g.addV(constant('person'))
</code></pre></div></div>

<p>This approach works — and it does so because <code class="language-plaintext highlighter-rouge">constant()</code> transforms each traverser to <code class="language-plaintext highlighter-rouge">'person'</code>, yielding the right label at the right time.</p>

<h2 id="the-side-effect-nature-of-inject">The Side-Effect Nature of inject()</h2>

<p>The confusion often stems from the fact that <code class="language-plaintext highlighter-rouge">inject()</code> behaves as a side-effect: it can insert one or more objects into the stream regardless of what’s already there, without transforming the current traverser. This can lead to potentially unexpected results when you chain multiple <code class="language-plaintext highlighter-rouge">inject()</code> calls. Consider:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gremlin&gt; g.inject(0).inject('x')
==&gt;x
==&gt;0
gremlin&gt; g.inject(0).constant('x')
==&gt;x
gremlin&gt; g.inject(0).inject('x').inject('y')
==&gt;y
==&gt;x
==&gt;0
gremlin&gt; g.inject(0).inject('x').constant('y')
==&gt;y
==&gt;y
</code></pre></div></div>

<p>With repeated <code class="language-plaintext highlighter-rouge">inject()</code> calls, each new invocation adds more items to the stream, but it doesn’t operate as a per-traverser replacement. On the other hand, <code class="language-plaintext highlighter-rouge">constant()</code> maps everything passing through to a new value.</p>

<p>For the case with <code class="language-plaintext highlighter-rouge">addV(inject('x'))</code> to set the label, it might be helpful to think of <code class="language-plaintext highlighter-rouge">addV()</code> more abstractly as a map-step where the incoming traverser is transformed to a new <code class="language-plaintext highlighter-rouge">Vertex</code>. We can demonstrate that as follows:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gremlin&gt; g.inject(0).map(__.inject('x'))
==&gt;0
gremlin&gt; g.inject(0).flatMap(__.inject('x'))
==&gt;0
==&gt;x
</code></pre></div></div>

<p>Note that the <code class="language-plaintext highlighter-rouge">map()</code> step ends up passing through the “0” because <code class="language-plaintext highlighter-rouge">inject('x')</code> passes that object through as the first item in its stream. A map-step will only ever take that first traverser. For sake of clarity, the second Gremlin traversal uses <code class="language-plaintext highlighter-rouge">flatMap()</code> and exhausts the entire child stream and therefore produces the “0” and the “x”.</p>

<p>Generally speaking, think of <code class="language-plaintext highlighter-rouge">inject()</code> as best for inserting or seeding values into a traversal flow and consider <code class="language-plaintext highlighter-rouge">constant()</code> as best for overwriting whatever traversers exist at any point in your pipeline.</p>]]></content><author><name></name></author><category term="snippet" /><summary type="html"><![CDATA[Distills the core distinction between Gremlin’s `constant()` and `inject()`.]]></summary></entry><entry><title type="html">Unique Vertex Label Anti-pattern</title><link href="https://stephen.genoprime.com/snippet/2025/06/19/snippet-19.html" rel="alternate" type="text/html" title="Unique Vertex Label Anti-pattern" /><published>2025-06-19T00:00:00+00:00</published><updated>2025-06-19T00:00:00+00:00</updated><id>https://stephen.genoprime.com/snippet/2025/06/19/snippet-19</id><content type="html" xml:base="https://stephen.genoprime.com/snippet/2025/06/19/snippet-19.html"><![CDATA[<h2 id="understanding-vertex-labels-in-graph-databases">Understanding Vertex Labels in Graph Databases</h2>

<p>Graph databases like those powered by Apache TinkerPop provide a robust framework for working with connected data. However, as with any powerful tool, there are ways to misuse it and one such common anti-pattern is using unique values for vertex labels. While this topic has been covered in other blog posts, Stackoverflow posts, books and graph database documentation, it still remains a trap that newcomers to graphs seem to make and therefore begs another treatment of the topic.</p>

<p>A vertex label is a string that categorizes vertices into logical groups. For example, a social network graph might have vertices labeled <code class="language-plaintext highlighter-rouge">person</code>, <code class="language-plaintext highlighter-rouge">post</code>, or <code class="language-plaintext highlighter-rouge">comment</code>. Labels help organize your data, enable efficient queries, and allow graph systems to optimize storage and indexing.</p>

<figure class="highlight"><pre><code class="language-groovy" data-lang="groovy"><span class="n">g</span><span class="o">.</span><span class="na">addV</span><span class="o">(</span><span class="s1">'person'</span><span class="o">).</span><span class="na">property</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="s1">'alice'</span><span class="o">)</span>
<span class="n">g</span><span class="o">.</span><span class="na">addV</span><span class="o">(</span><span class="s1">'person'</span><span class="o">).</span><span class="na">property</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="s1">'bob'</span><span class="o">)</span></code></pre></figure>

<p>Here, both vertices are labeled ‘person’, making it easy to query all people in the graph.</p>

<h2 id="the-unique-vertex-label-anti-pattern">The Unique Vertex Label Anti-Pattern</h2>

<p>A common mistake is to use a vertex label as if it were a unique identifier or a property. For instance, someone might assign a label to each vertex that is unique to that vertex:</p>

<figure class="highlight"><pre><code class="language-groovy" data-lang="groovy"><span class="n">g</span><span class="o">.</span><span class="na">addV</span><span class="o">(</span><span class="s1">'user_1'</span><span class="o">).</span><span class="na">property</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="s1">'alice'</span><span class="o">)</span>
<span class="n">g</span><span class="o">.</span><span class="na">addV</span><span class="o">(</span><span class="s1">'user_2'</span><span class="o">).</span><span class="na">property</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="s1">'bob'</span><span class="o">)</span></code></pre></figure>

<p>Or, worse, use a label that is derived from a property value:</p>

<figure class="highlight"><pre><code class="language-groovy" data-lang="groovy"><span class="n">g</span><span class="o">.</span><span class="na">addV</span><span class="o">(</span><span class="s1">'alice'</span><span class="o">).</span><span class="na">property</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="s1">'alice'</span><span class="o">)</span>
<span class="n">g</span><span class="o">.</span><span class="na">addV</span><span class="o">(</span><span class="s1">'bob'</span><span class="o">).</span><span class="na">property</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="s1">'bob'</span><span class="o">)</span></code></pre></figure>

<p>This approach misuses the label concept and leads to several problems.</p>

<h2 id="consequences-of-misusing-vertex-labels">Consequences of Misusing Vertex Labels</h2>

<p>Vertex labels are intended for grouping and filtering, not for uniqueness. When you use unique labels, you lose the ability to efficiently query a category of vertices. For example, to find all users in the graph above, you would have to scan every possible label, which is impractical:</p>

<figure class="highlight"><pre><code class="language-groovy" data-lang="groovy"><span class="c1">// This is not possible if every user has a unique label!</span>
<span class="n">g</span><span class="o">.</span><span class="na">V</span><span class="o">().</span><span class="na">hasLabel</span><span class="o">(</span><span class="s1">'person'</span><span class="o">)</span></code></pre></figure>

<p>Instead, you would have to use a property filter, which may not be as efficient as a label-based index:</p>

<figure class="highlight"><pre><code class="language-groovy" data-lang="groovy"><span class="n">g</span><span class="o">.</span><span class="na">V</span><span class="o">().</span><span class="na">has</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="n">within</span><span class="o">(</span><span class="s1">'alice'</span><span class="o">,</span> <span class="s1">'bob'</span><span class="o">))</span></code></pre></figure>

<p>But this only works if you know all possible names, and it may not leverage label-based indexes.</p>

<p><a href="https://aws.amazon.com/neptune/">Amazon Neptune</a> and other graph databases optimize queries by using labels as a primary filter. If every vertex has a unique label, Neptune cannot use label-based indexes to speed up queries. This forces the engine to scan the entire graph, degrading performance—especially as the graph grows.</p>

<p>Additionally, Neptune treats each distinct vertex label as a predicate. If you have thousands or millions of unique labels, you risk hitting performance limits due to high predicate counts. <a href="https://docs.aws.amazon.com/neptune/latest/userguide/gremlin-traversal-tuning.html">Neptune’s documentation</a> specifically warns about the negative impact of high numbers of predicates on query performance.</p>

<p>Graph visualization tools often use vertex labels to group and color nodes. If every vertex has a unique label, visualizations become cluttered and lose their ability to convey meaningful structure. Instead of seeing clear categories (like “person” or “post”), you see a sea of indistinguishable nodes. In addition, these tools are likely not optimized for this anti-pattern and may encounter basic performance problems as a result.</p>

<h2 id="practical-examples-and-correct-usage">Practical Examples and Correct Usage</h2>

<p>Consider a graph where each user has a unique label:</p>

<figure class="highlight"><pre><code class="language-groovy" data-lang="groovy"><span class="n">g</span><span class="o">.</span><span class="na">addV</span><span class="o">(</span><span class="s1">'user_1'</span><span class="o">).</span><span class="na">property</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="s1">'alice'</span><span class="o">)</span>
<span class="n">g</span><span class="o">.</span><span class="na">addV</span><span class="o">(</span><span class="s1">'user_2'</span><span class="o">).</span><span class="na">property</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="s1">'bob'</span><span class="o">)</span></code></pre></figure>

<p>To find all users, you cannot use a label filter, so you must resort to property-based queries, which are less efficient:</p>

<figure class="highlight"><pre><code class="language-groovy" data-lang="groovy"><span class="n">g</span><span class="o">.</span><span class="na">V</span><span class="o">().</span><span class="na">has</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="n">within</span><span class="o">(</span><span class="s1">'alice'</span><span class="o">,</span> <span class="s1">'bob'</span><span class="o">))</span></code></pre></figure>

<p>If you add more users, the query becomes increasingly unwieldy and slow.</p>

<h2 id="the-correct-approach">The Correct Approach</h2>

<p>Use vertex labels to group vertices by type, and use properties for unique identifiers or other attributes. For example:</p>

<figure class="highlight"><pre><code class="language-groovy" data-lang="groovy"><span class="n">g</span><span class="o">.</span><span class="na">addV</span><span class="o">(</span><span class="s1">'person'</span><span class="o">).</span><span class="na">property</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="s1">'alice'</span><span class="o">)</span>
<span class="n">g</span><span class="o">.</span><span class="na">addV</span><span class="o">(</span><span class="s1">'person'</span><span class="o">).</span><span class="na">property</span><span class="o">(</span><span class="s1">'name'</span><span class="o">,</span> <span class="s1">'bob'</span><span class="o">)</span></code></pre></figure>

<p>Now, you can efficiently query all people:</p>

<figure class="highlight"><pre><code class="language-groovy" data-lang="groovy"><span class="n">g</span><span class="o">.</span><span class="na">V</span><span class="o">().</span><span class="na">hasLabel</span><span class="o">(</span><span class="s1">'person'</span><span class="o">)</span></code></pre></figure>

<p>Or find a specific person by name:</p>

<figure class="highlight"><pre><code class="language-groovy" data-lang="groovy"><span class="n">g</span><span class="o">.</span><span class="na">V</span><span class="o">().</span><span class="na">has</span><span class="o">(</span><span class="s1">'person'</span><span class="o">,</span> <span class="s1">'name'</span><span class="o">,</span> <span class="s1">'alice'</span><span class="o">)</span></code></pre></figure>

<p>This approach leverages label-based indexing, improves query performance, and makes your graph easier to understand and visualize.</p>]]></content><author><name></name></author><category term="snippet" /><summary type="html"><![CDATA[Warns against the anti-pattern of unique vertex labels in graph databases and advocates for categorical labeling.]]></summary></entry></feed>